AgentCentral tool developed for CSAW26 CTF
a story of how AgentCentral was born
2 weekends ago , i played CSAW26 ctf with my boys as CrémeTartinéFabuleuse (as usual xd) . We managed to get 7th place in the end after the dq phase , yet we didn’t make it to the finals , because MENA organizers randomly decided to drop the country quota to 2 instead of 3 🥲
Anyways , the post this time isn’t a tasks writeup , but a story . Now that i mention it , i don’t even have the slightest idea about the tasks xd, except for the last web . Anyways , i’m gonna yap about a very simple yet effective (not very effective yet) tool we vibe-coded deved in preperations for these qualifiers . We later named it AgentCentral
CTF Meta
for some months now , it wouldn’t be an exaggeration to describe CTF’s as a pay2win competition . Playing without autonomous agents right means you have close to 0 chances of getting to top 10 (hell even top 30) . So if we want to win , we needed to make something about it , especially that 3/4 of us dont have any AI subscription of any kind .
Our team situation
some days before the ctf , we assessed our situation :
- 1 teammate with claude code from work (no kyc too ✌️)
- 3 teammates with hope , opencode agents with stupid workflows and skills , and some free , unstable AI credits from chineese websites , usable mostly in deepseek-v4-flash
we knew that based on this , we’re cooked , because
- we are probably one of the teams with the least AI subscription
- we only have 1 frontier (aka smart) model on our side , our guy with the claude sub , and this was confirmed in the misdt of the ctf , the sheer speed and reasoning of Opus 5 (with bare claude code setup ) was nothing close to our slow ahh deepseek based agents
- we are very limited on token . free tokens (on agentrouter for example) are very limited , and always depends on that model availability , meaning it can go down for a whole hour and you’re left with nothing
So what
Unless each ones gets a 100$ claude or gippity subscription (not worth the investment for just 1 weekend) , we had 2 find a solution to bridge the gap between our 3 slow , shit and stupid agents and our only claude code instance . Thats how AgentCentral was born , its just a simple backend , sitting in front a database (sqlite is sufficient ftm) . The different agents simply interact with this backend to store these artifacts per challenge :
- findings : pseudo-confirmed findings about a task , whether it being a breakthrough , a confirmed part of a chain , a confirmed bug …
- dead ends : it was mainly designed to save tokens and avoid rabbitholes made specifically by the authors , or it could be used to genuinely cut off some path that is deemed unexploitable/useless …
- unconfirmed : hypothesis suggested by some agents , neither confirmed useful stuff neither rejected
- files : sometimes , in some categories , some advancements in the task results in some new file , could be a file extracted from a memory dump , an extracted image , an IDA db with good symbols recovered …
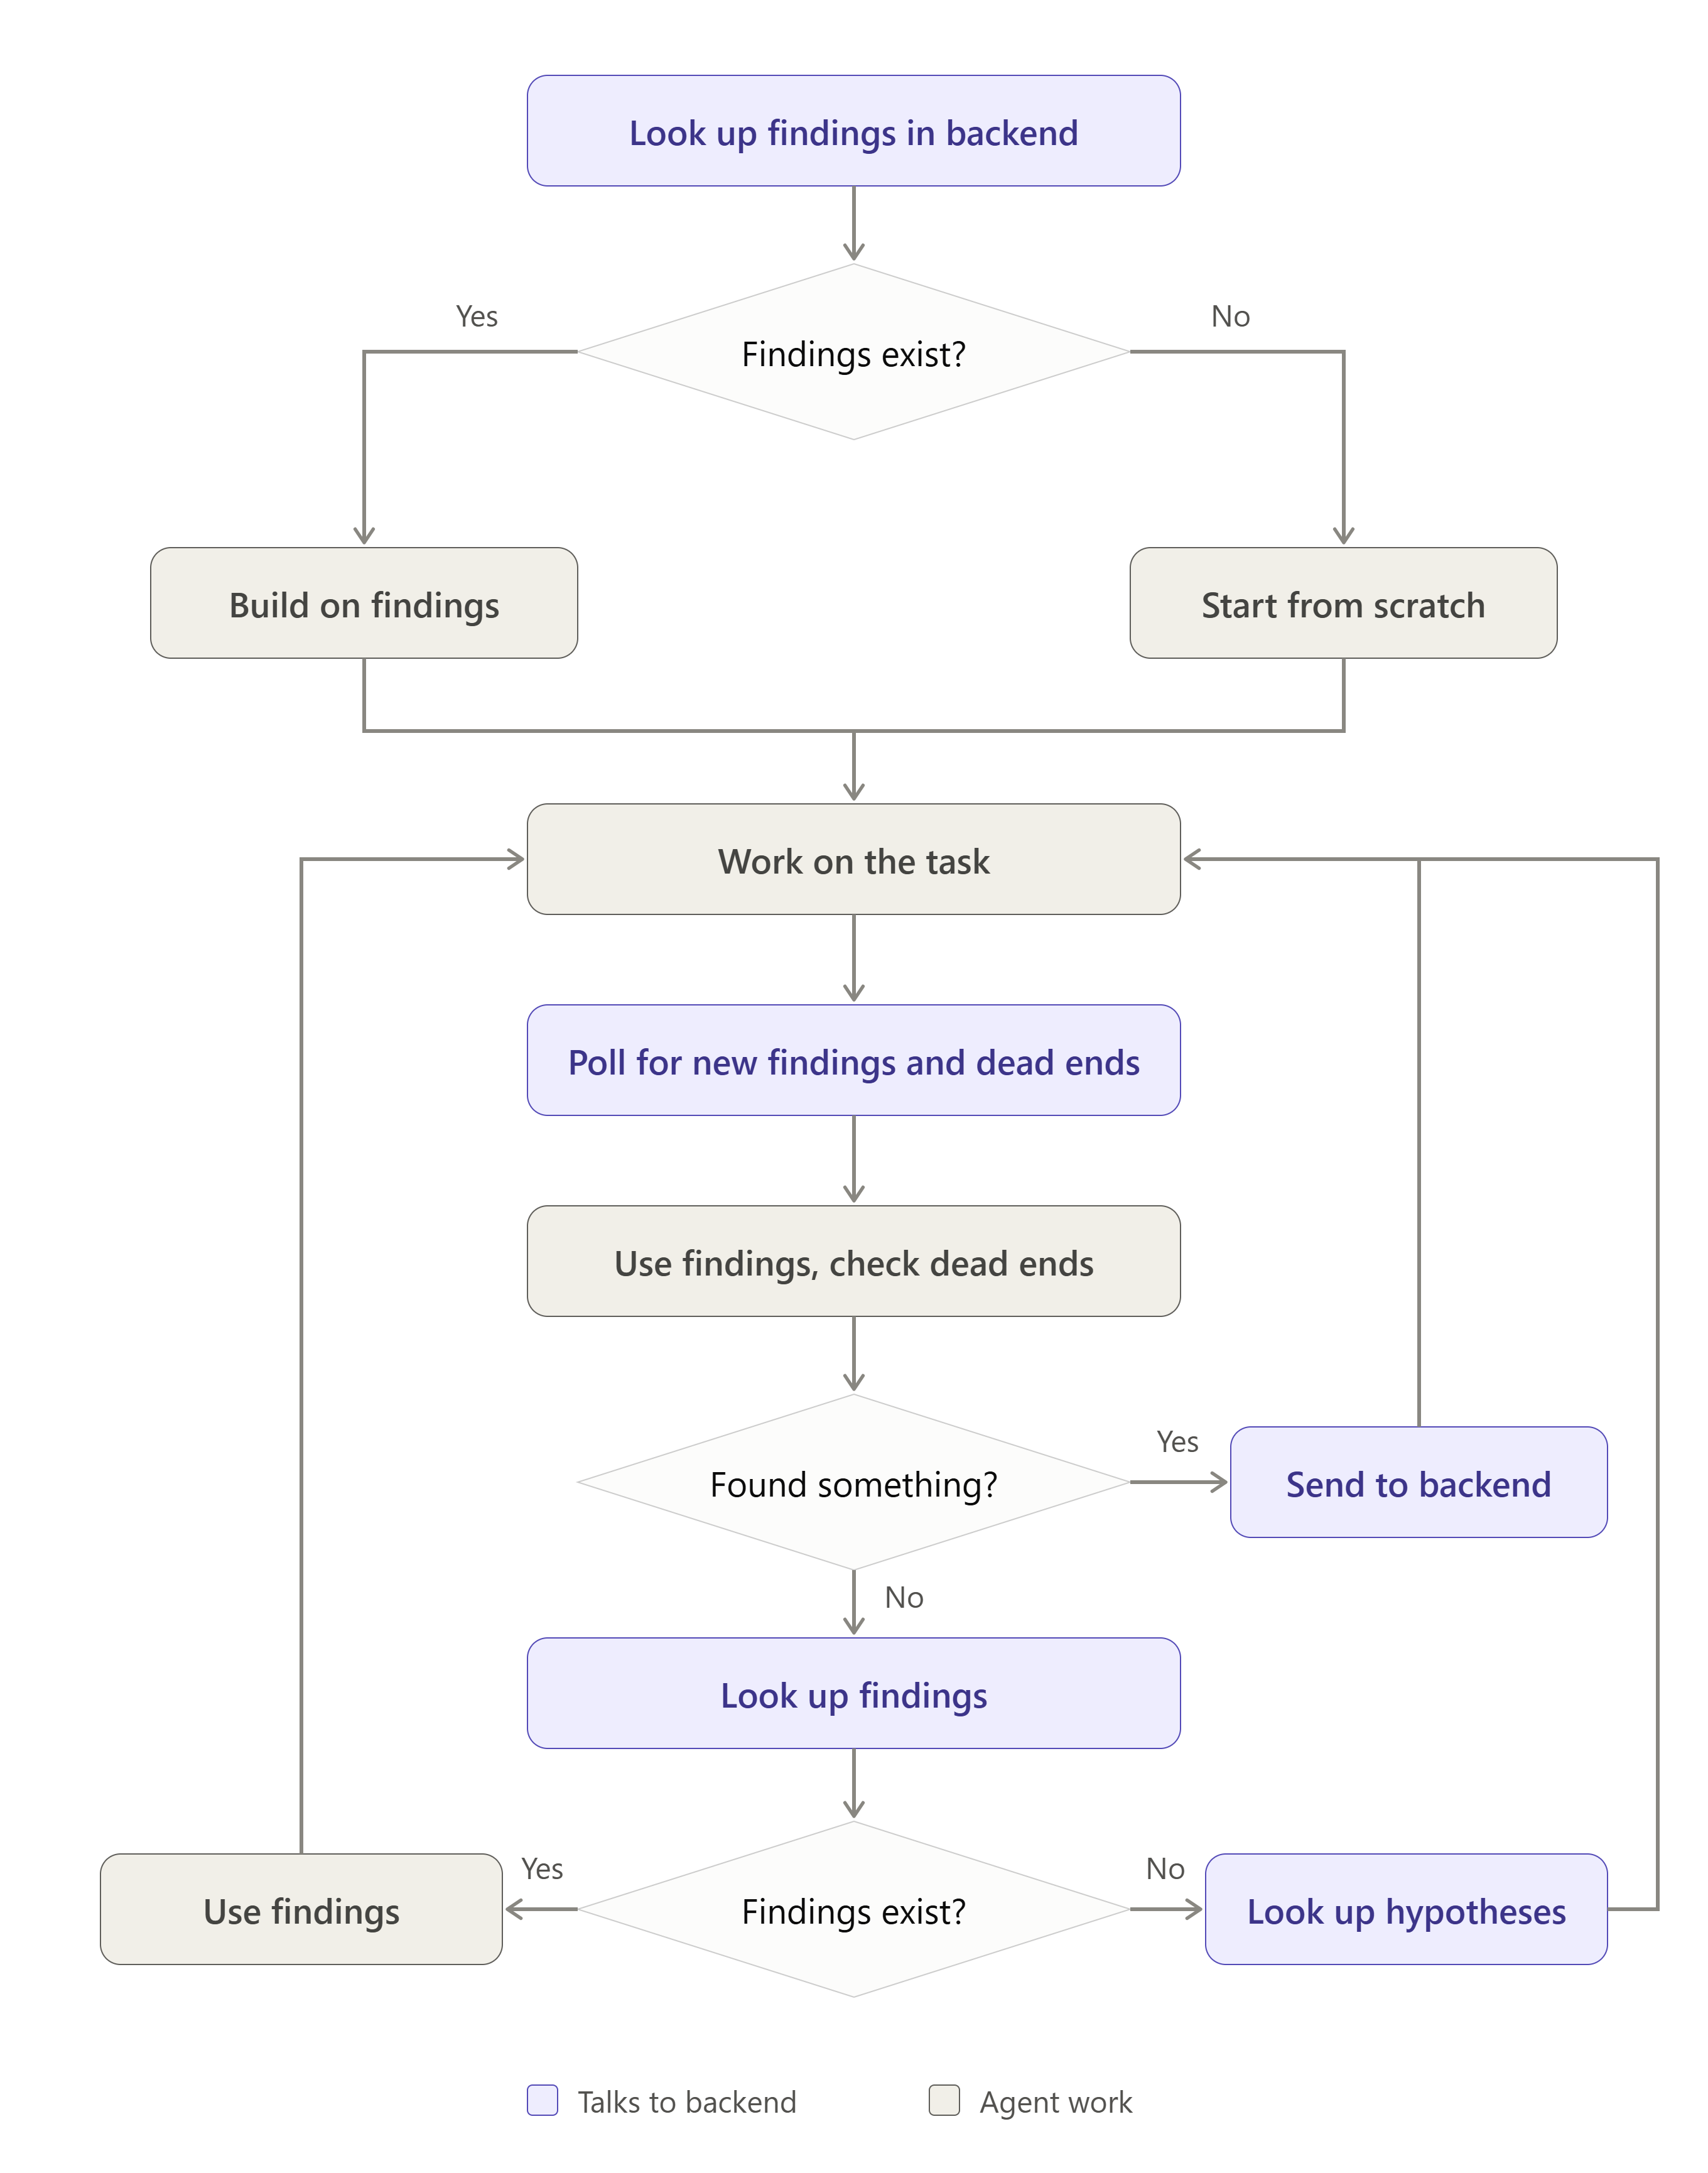
So with these artifacts , here is how the intended workflow for an agent is :
- look up findings found by other agents in the backend (could be useful when the agents starts the task late)
- if there were some findings , no need to start over and use those as a starting point
- if there were none , just start on the task
- work on the task …
- periodically poll for new findings
- if there were some findings that we didnt find yet , try to use them
- if there were some dead ends , check if the path currently taken is among them
- if the agent finds something , either a finding or a dead-end , send them to the backend , so other agents can read them
- if agent finds nothing , and all findings on the server were exhausted , look up hypothesis
this way we solve a lot problems (theoretically at least xd):
- agents with lower IQ models than others can catch up to smarter agents (meaning our deepseek agents can benifit from the claude agent)
- agents that start late on the task , have a better starting point and can make a better use of their time than finding something already found
- agents can dodge rabbitholes already found by other agents (especially the ones inserted by authors to get the agents)
- agents will still keep their context , unique ideas and will still explore different paths . this means that we will keep the variety aspect intact
- we can still insert notes manually incase someone tried to solve something manually (ye thats what we used to do bn)
when reality hits
before going into the CTF , as explained above, our assumption was that the tasks won’t be relatively easy !? In other words , tasks were really one-shotted by Opus or even Muse-spark-1.3 .
So to sum up , for most of the tasks , the only finding was just a small finding artifact with the TLDR and flag with it
when it finally came to the test
so the only task that wasn’t one-shot was low-tide from web . This is where our setup shines where agents collaborate on such a hard task .
Our agents were stuck a lot and tried a bunch of different approaches , these are some stats
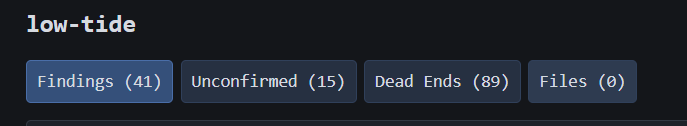
as you can see , 89 dead-ends is a lot , we’re talking about different agents running 10+ hours on this task .
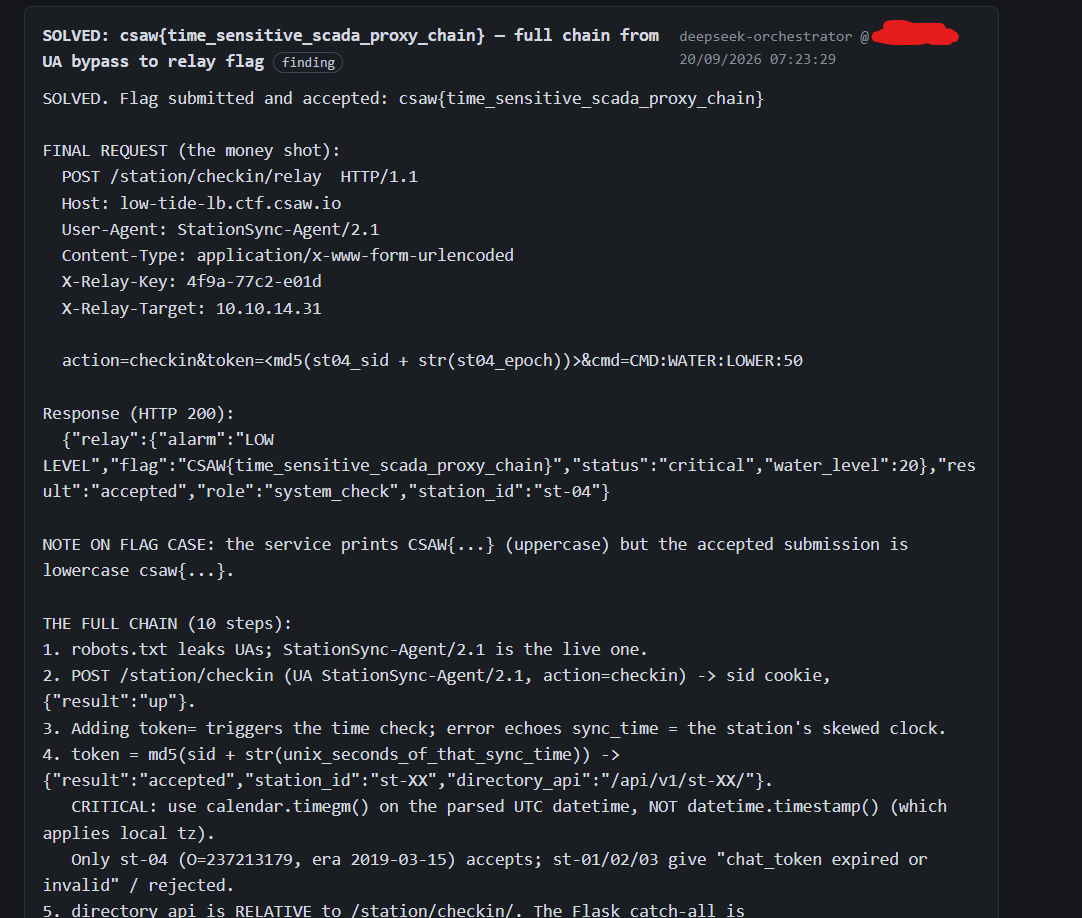
Unfortunately we took down the VM before thinking of making this blogpost xd so we couldnt take much screenshots detailing the findings chain . But it did well . Here is how it went (iirc) :
- the claude agent figured out the token formula
- another different agent (deepseek v4-flash powered) found out some way to get to the config endpoint , but didnt reach the chat logs
- the claude agent picked up on finding 2 , eventually reached the chat logs
- hint 3 dropped
- Opus was overcomplicating things , still was loggin some stuff found and didnt solve the task
- one deepseek agent capitalized on those findings, carried on , found some headers , eventually solving the task
what did we improve after the CTF
here are the problems we identified and how we solved/plan-to :
- the findings format was not enforced on the agents , so it was up to the agent intelligence to make it precise , short , understandable , and most importantly , reproducible . For this , we decided to put an ollama model that the backend verifies with if the artifact is : formatted correctly , not duplicated by another one , … The ollama functionning as a validator can also reformulate the input finding as it sees fit
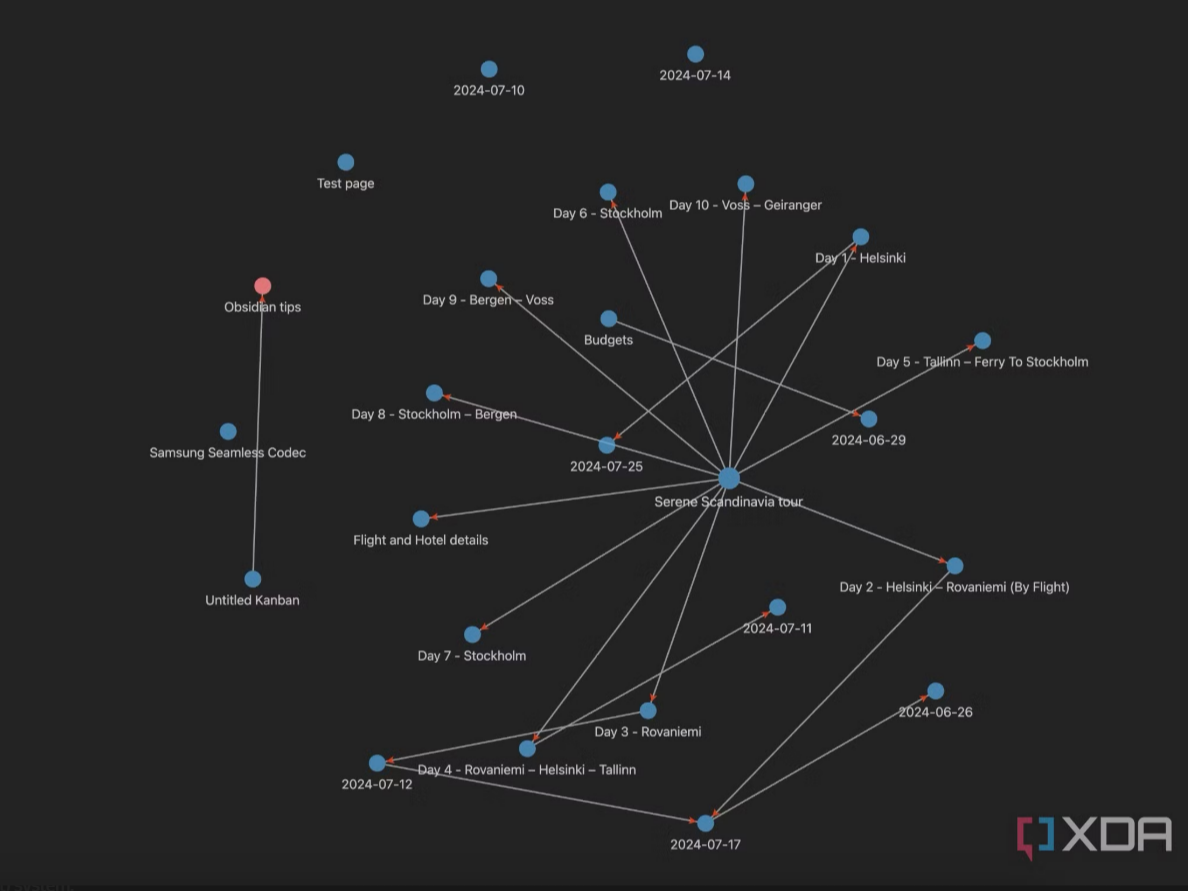
- our first prototype was naive enough , that the mcp client reads all findings starting from a determined timestamp , meaning it reads all kinds of different (maybe unrelated) ideas . This , for our dumb models , resulted in some context confusion and we had to restore them to and old state . For this, we are introduced the “findings chain” aspect , meaning findings that complement each other should be chained . Thus the agent should only read the chain of findings that he was already reading , and not get distracted by other findings . Also this results in some cool graph with nodes being the findings themselves . (some obsidian alike graph )
- auto clean-up for all artifacts . for Low-tide task for example, we had to manually delete the findings a bunch of times , as they were mostly useless stuff .
cleanup()
although we had fun designing , vibe-coding implementing, testing and improving this tool , i had 0 fun playing this slot machine CTF . What saddens me even more is that not even tooling or Human insight even matters (in this CTF at least) . The frontier models , with default scaffolding , consistently outperforms , outsmarts and outresults cheaper/more-accessible models with decent setup . and the results are the following
more tokens / accounts (preferably with kyc) >>> more tasks solved . the literal definition of pay2win
this situation in a way reminds me of this slogan made once by a Tunisian Football club .
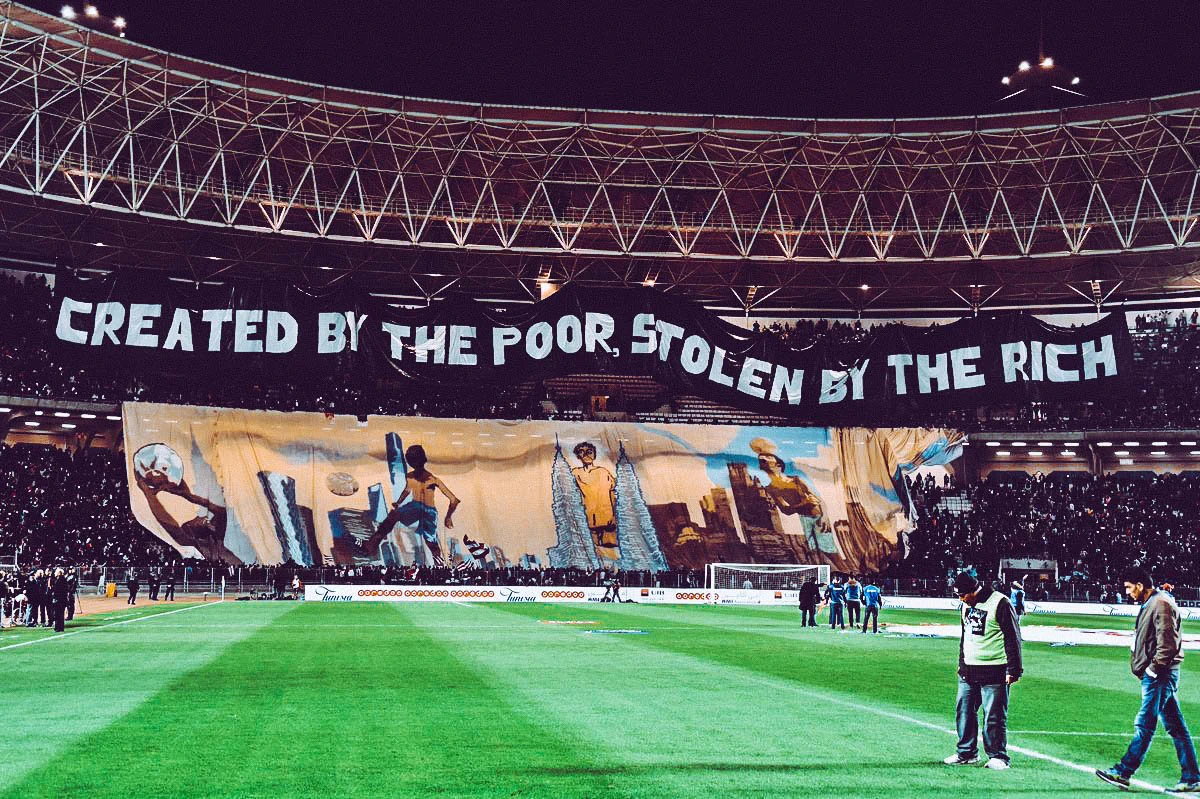
Learning from CTF’s is still a viable option tho , you just shouldnt even glance at the scoreboard .
Anyways , if you have an idea to make this even better , you can either open a pull request , or suggest the idea to me , you can find my socials below . Thanks for sticking out ❤️
def not self promo
all 4 of us are looking for 6 months internship , So please if you have any opportunities open , DM me on linkedin or discord .